Design engineering2026Research tool · 12 min

Research studies, crafted and hosted for you.

You say what you want to learn. Testify plans the study, updates your prototypes so the test is fair, then hosts it for your team. On its first real study, it caught a flaw before anyone took part.

Role
Designer and builder, solo with AI
Context
Testing dealership software at myKaarma
Timeline
2026, in three phases
Built with
HTML, Cloudflare and Gemini

Try it

Plan a study the way Testify does.

Say what you want to learn. Testify evens out the prototypes so the test is fair and builds the session.

TTestify/ Parts UI · pre-approved vs recommendationsSample plan · the first real study

What do you want to learn?

🎙 Talk it through · in the real tool
The real plan from the Parts study.

Press Plan it to watch the study build itself.

1Reads what you want to learn
parts userspre-approvedvs recommendationswhich works better → A vs B
2Updates both prototypes0 changes
ACurrent
Pre-approvedFetch◎
DMS error
Recommended+
Part not found+
BProposed
Approved at write-up
Pre-approvedFetch◎
Recommended
DMS error+
Part not found+
  • +Same kinds of lines in A and B
  • +A part-not-found error in both
  • ◎“Done” tagged on the right Fetch button
3Builds the session8 activities
  1. 👋Welcome
  2. ⏱First look5 s
  3. 🏷Sort the lines
  4. 👆First click
  5. AParts taskscored by state
  6. BParts taskscored by state
  7. ⚖Which is better?
  8. ✓Wrap-up
Versions alternateP1ABP2BAP3ABP4BAP5ABP6BA
4Checks what else differs0 to fix
  • A developer-only alert shows in BFixRemoved from B
  • “Approved at write-up” and “Approved” look alikeFixA task now asks how each line got approved
  • B puts pre-approved work in its own sectionIntendedThis is what's being tested
5Updates the prototype, same linkv1
ACurrent
BProposed
CNeutral color+

Version C keeps B's layout but drops the green. That shows whether B's layout is what helps, or whether its color is what confuses.

🔗 Participant linkunchangedUpdateLive: v1 · 2 versions
Order rotatesP1ABCP2BCAP3CAB

01 · Plan

The problem

Off-the-shelf tools assume a world I don't work in.

Testing tools like Maze and UserTesting assume three things: clickable Figma mock-ups, consumer participants, and a researcher with time to design every study by hand. My work breaks all three. My prototypes are written in code, with real states and real errors, and teams that test seriously have moved the same way. Click-tracking on a static Figma screen can't tell whether someone actually finished a task. My participants are parts-counter staff and service advisors, who have minutes to spare rather than hours. And running the test was never what took most of my time. The slow part was deciding what success meant, which activity would measure it, and whether the two versions were even a fair comparison. Existing tools give no help there. They start at "add a task".

PrototypesBuilt in code, rather than Figma mock-upsReal states, real errors, scored inside the prototype
ParticipantsBusy professionalsParts counter staff with minutes to spare. Every task has to earn its place
The researcherMe, part timeThere's no dedicated research team, so the judgment has to live in the tool
Decide what "better" means before you look at the data. It's a habit I brought from conversion work (testing changes to get more people to sign up or buy), turned into software. The planner above puts that sentence into practice.

02 · Build

Phase 1

I built the study builder first. It was the wrong tool.

The first version was a study builder, like Maze: six test types, a join code, shared storage and a heat map of first clicks. It fell short in three ways, and all three pointed to the planning that happens before a study is built.

A study in Testify: seven steps down the left, from Start to Results, with the Plan step open.
Where it ended up: seven steps, from Start to Results. Phase 1 had only the Build and Run steps.
1
Success was self-reported.A participant who gave up and clicked "Completed" looked like a success.
2
It could only run a study I had already designed.The thinking still happened in my head, at five o'clock at the end of a long day.
3
It had no idea of versions.Comparing version A with version B meant running two studies and comparing them by eye.

Try the first gap yourself

Said done versus actually done.

Task: fetch the part for the pre-approved line.
Diagnosis · approved at write-upno parts · labor only
nothing to source
CV axle boot · awaiting decision44305-TBA-A01 · qty 1
Brake pads · pre-approved45022-SNA-A00 · qty 1
Try finishing the task, or just say you did.
How Testify reports it
Reached the right state0
Said done, but hadn't0
Wrong-line edits0

The task only counts as done when the participant reaches a tagged element in the prototype, here the right Fetch parts button. "Said done, but hadn't" became its own group in the results, and one of the most useful signals in the tool.

02 · Build

Phase 2 · What I decided

Move the tool upstream, into planning.

The pivot was changing the tool's job. Instead of helping me run a study I had designed, Testify now helps me design it, starting from the goal. Each rule below is one piece of research judgment I had been carrying in my head, made explicit and handed to the tool.

Rule 1

Every metric names the activity that measures it.

You can't leave the Plan step with a metric that nothing measures. Each success metric says which direction counts as a pass, and which activity produces the number. In phase 2 each one also had a target, such as "at least 80% of lines classified correctly". Anything left unmeasured is flagged.

In phase 3, targets became optional. Comparing versions already tells you which is better. A target only answers whether the winner is good enough, and a junior designer shouldn't have to invent one just to get started.

This is the habit from conversion work. Decide what "better" means before you see the data, so the data can't talk you into a story afterwards.

ShippedResearch methodOwn practice
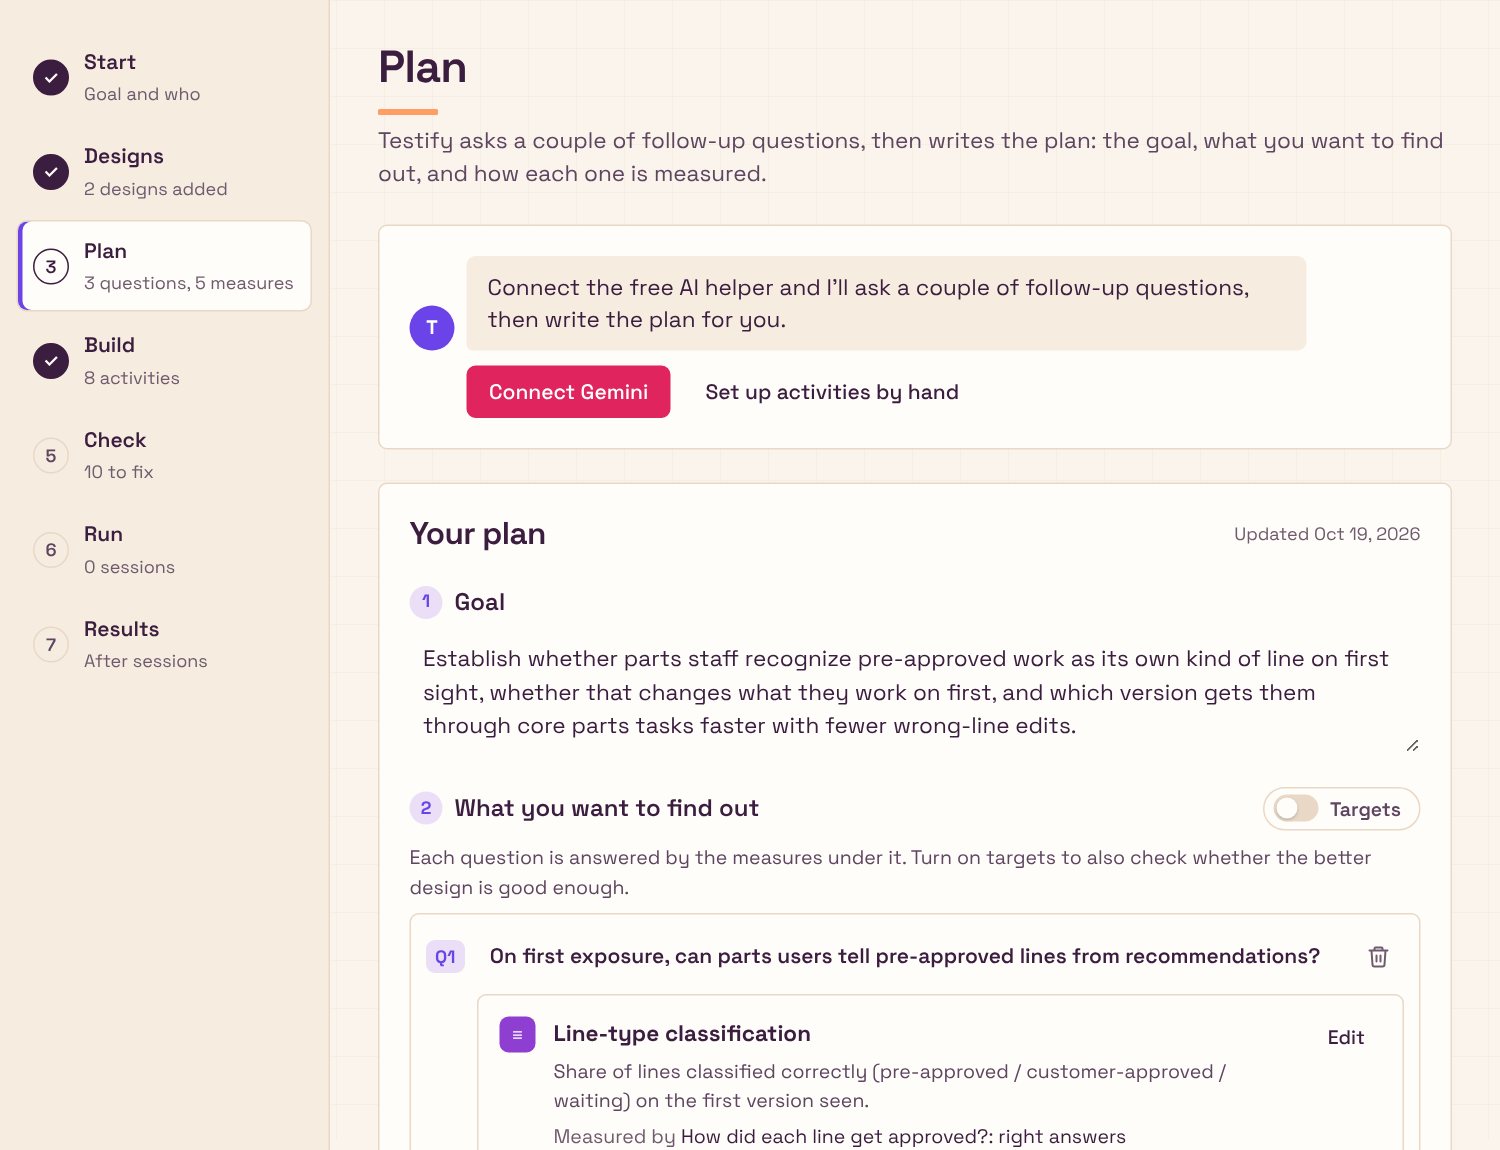
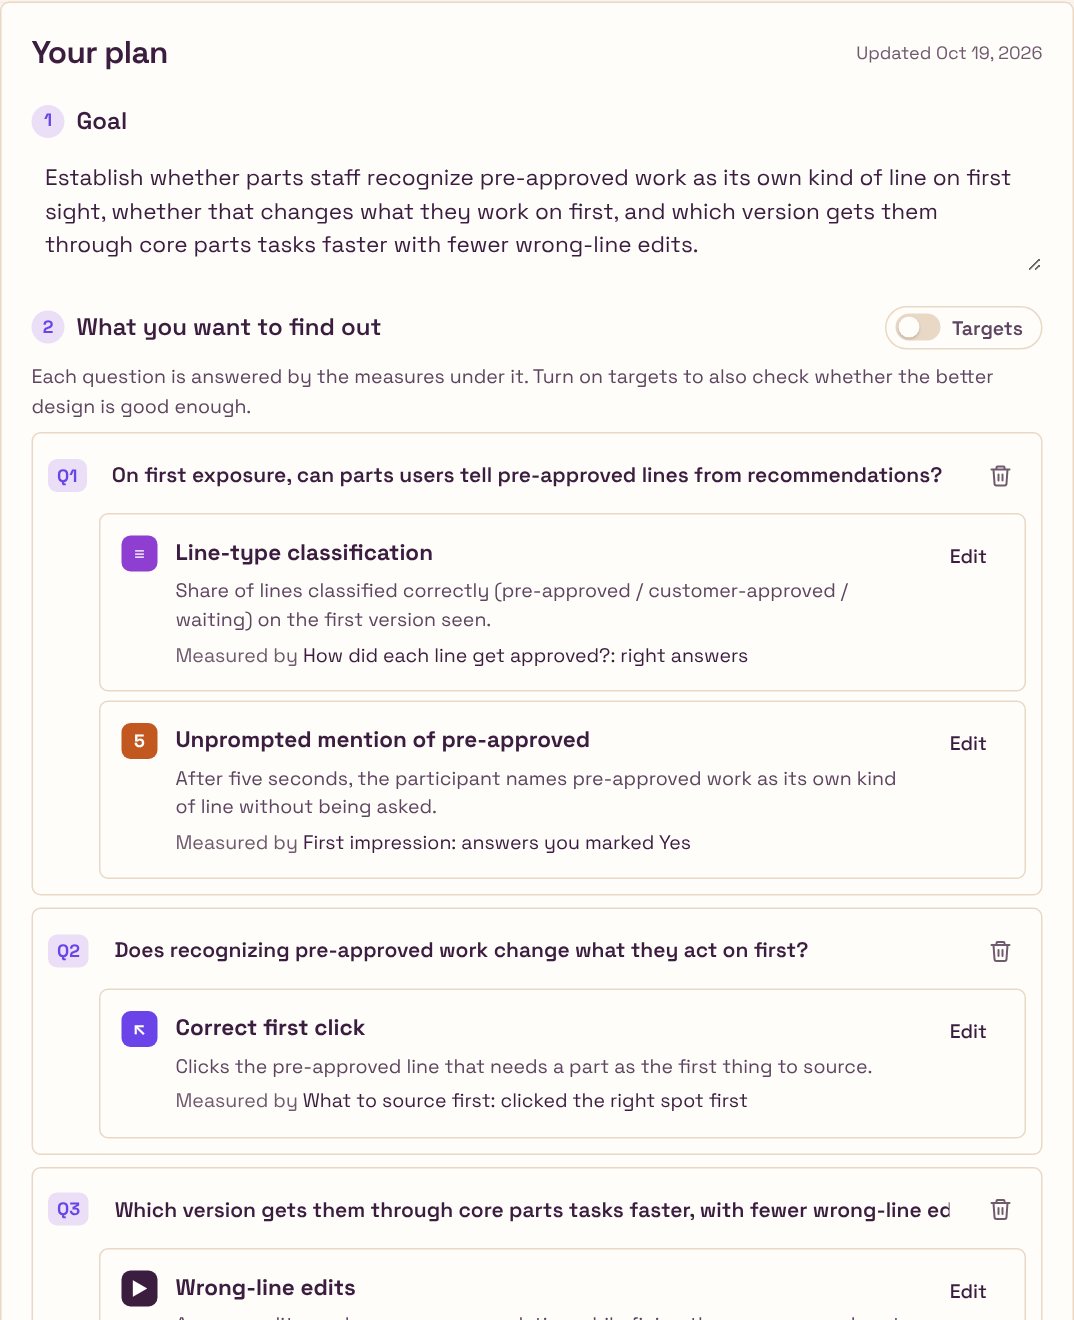
The plan: the goal, then each research question with the measures that answer it and the activity behind each one. Targets are a switch, off by default.
Each measure says which activity produces it. Targets are a switch, off unless you want them.

Rule 2

Tasks finish when the prototype reaches the right state.

A prototype task is complete when the participant actually reaches the tagged element, rather than when they say they're done. You tried this above. Testify tags the prototypes itself. You drop in an HTML file, and it finds the buttons and lines each task refers to, marks them, and hands you back a tagged copy.

ShippedMeasurementPhase 1 failure
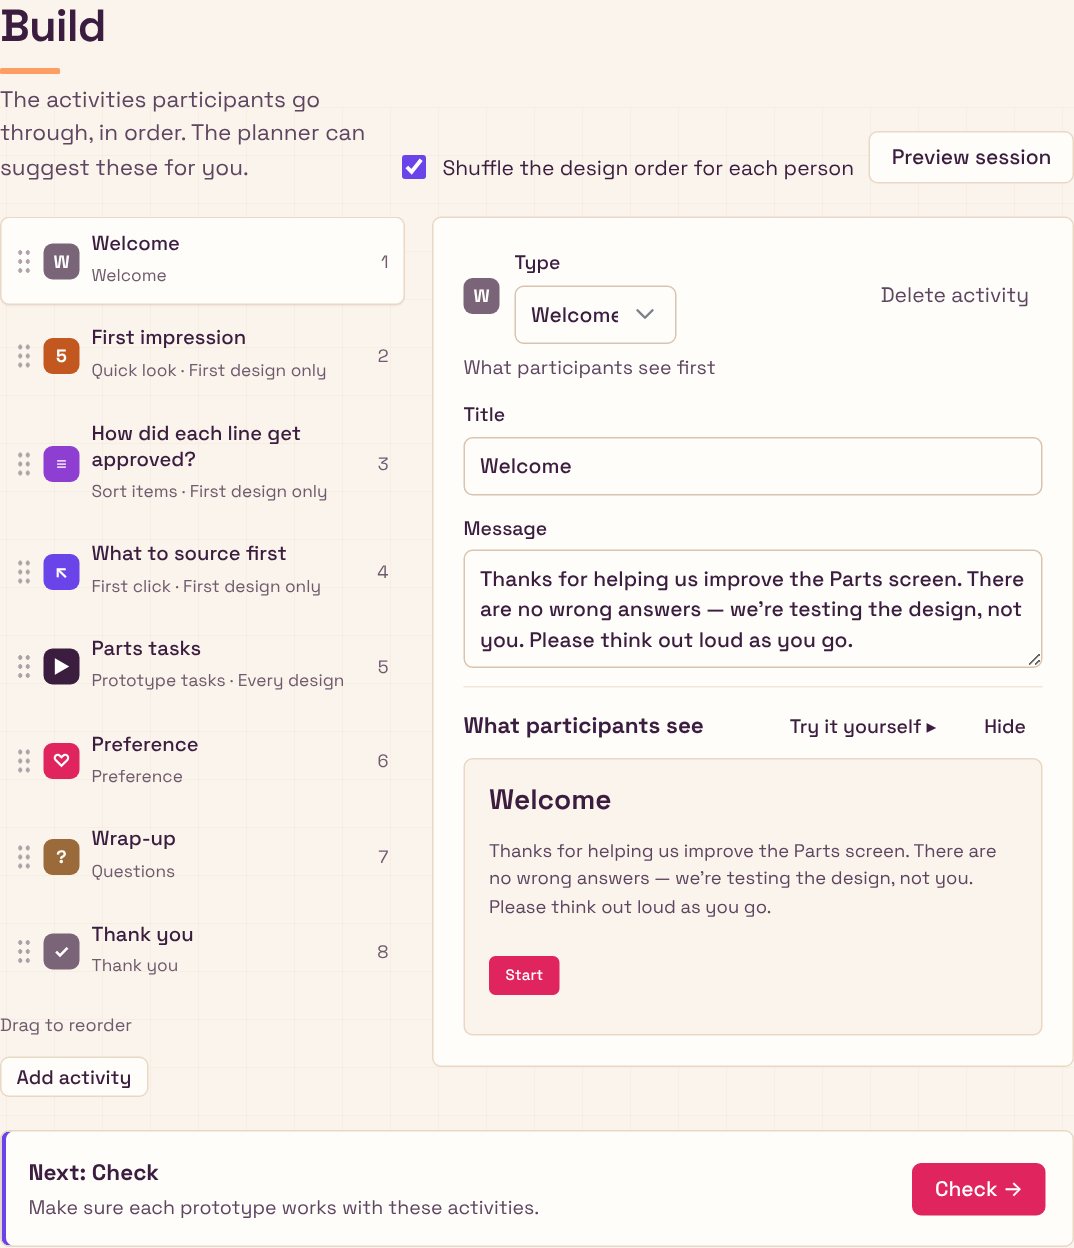
The Build step: eight activities in order, each marked First design only or Every design, with a preview of what participants see.
Eight activities, set up from the plan. The prototype tasks score themselves.

Rule 3

Comprehension questions run on the first version only.

By the time participants see the second version, they've already learned the concept. Asking "what is this?" again would measure their memory instead of the design. So three activities run only on the first version a person sees: the five-second first impression, sorting lines into types, and the first click. Task performance is measured on every version. It is the kind of judgment a researcher carries in their head, and the kind that gets skipped at five o'clock.

ShippedExperimental designOwn practice
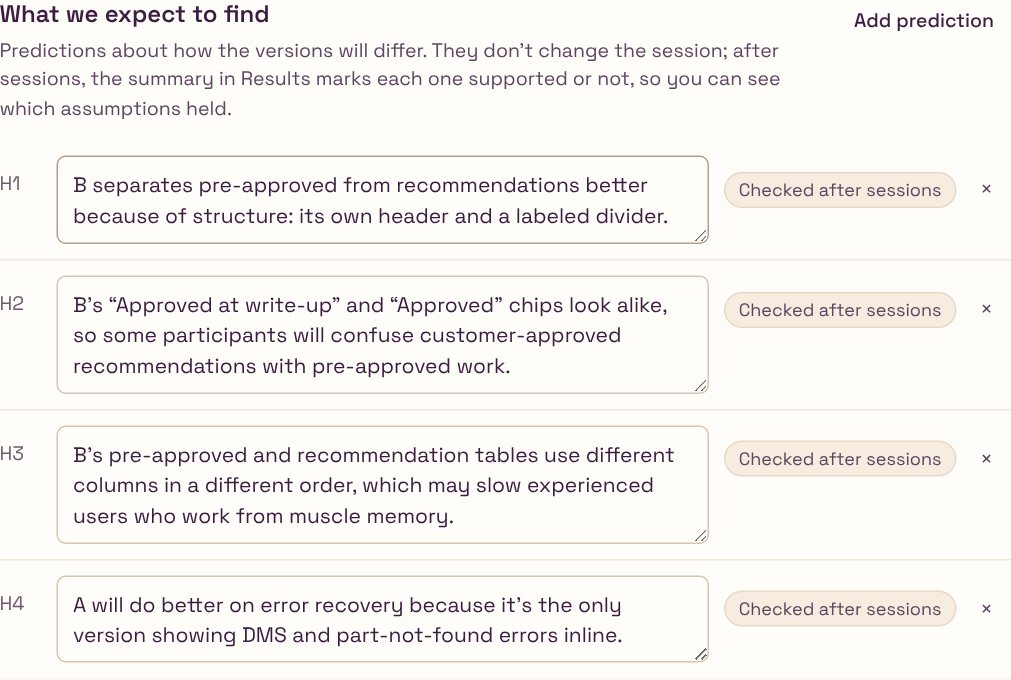
What we expect to find: four predictions, each checked after sessions.
Predictions written before the session, so the summary can mark each one supported or not afterwards.

Rule 4

Flag what differs besides the design.

The planner checks whether the versions differ in anything besides the thing being tested, such as different data or missing error states. It lists those as must-do fixes before testing, kept apart from optional ideas. Each fix can be marked Done or Skipped, and a count shows what's left.

On the very first real plan, this caught a flawed A/B comparison before any participant's time was spent. That alone paid for the rebuild.

ShippedValidityParts study
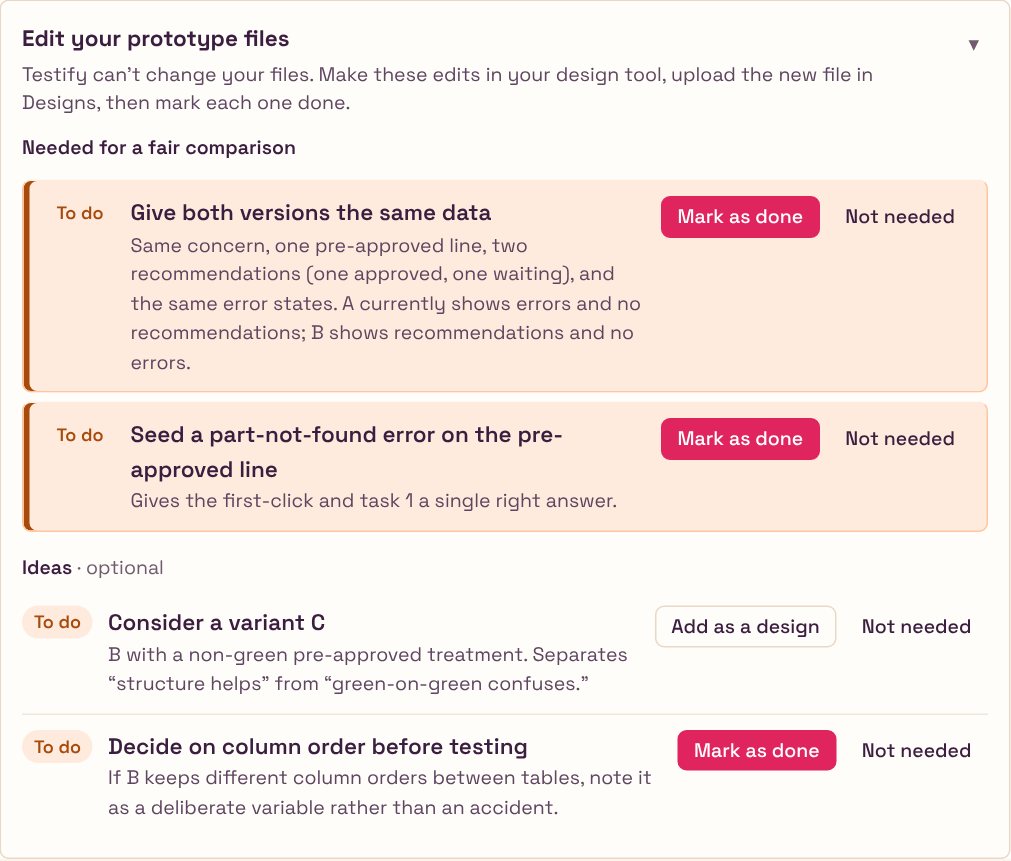
Edit your prototype files: what's needed for a fair comparison, such as Give both versions the same data, kept apart from optional ideas like a variant C.
Must-do fixes and optional ideas, kept apart. The test can't go ahead until the must-dos are done.

Rule 5

Anything safe to automate is automated, with undo.

I wanted to spend my time on judgment rather than setup. Session setup, prototype tagging and pulling in results happen on their own, and every automatic action can be undone. Each step ends with a banner pointing to the next one, so it's always clear what to do now.

Participants need no account. Since phase 3, everyone gets the same link, and the order of the designs is shuffled for each person. One Publish button puts the study online, and Update republishes after every change without changing the link. A single downloadable HTML file stays as a backup. Answers go to PostHog, Supabase or Google Sheets, services I already control. The keys that can read the results never leave my browser.

ShippedAutomationOwn usage
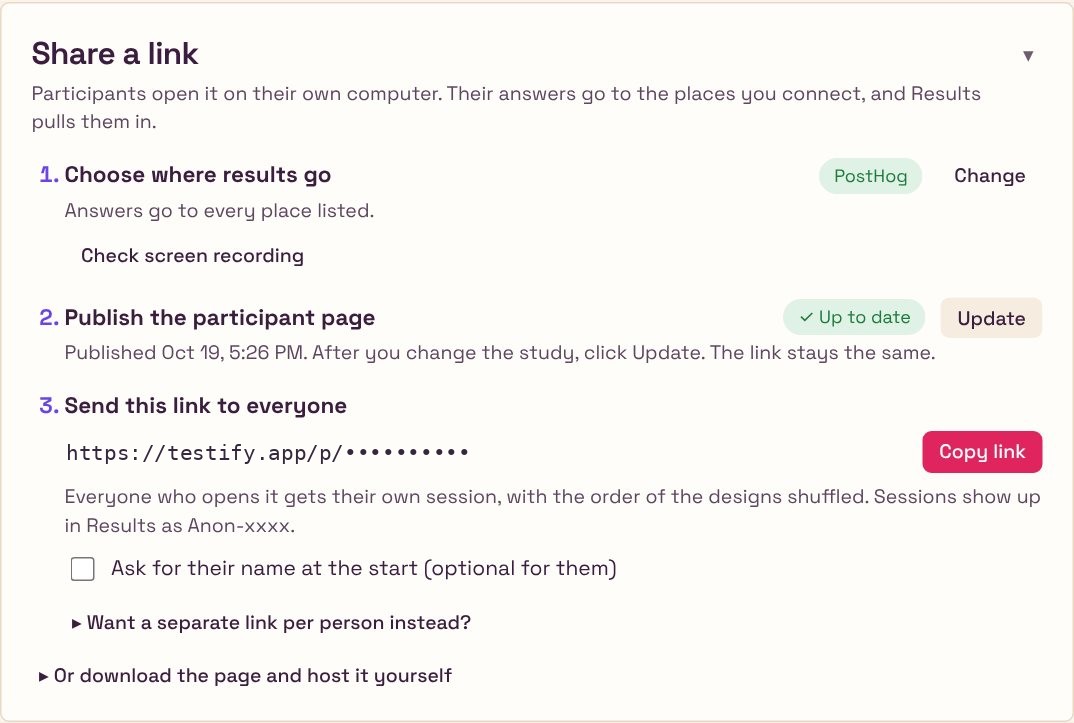
Share a link: answers go to PostHog, the participant page is published and up to date, and one link goes to everyone.
It used to take four steps, including downloading a file and hosting it. Now it's Publish, and Update after a change. The link stays the same.

03 · Run

The Parts study

The first real plan caught the flaw before the test did.

I used Testify's first real plan on a live question at myKaarma. Which version of the Parts screen works best for parts staff? And do they understand that the new pre-approved section (work the customer has already agreed to) is different from recommendations (extra work still waiting for the customer's decision)? The plan had three research questions, each with the activity that measures it and a target decided in advance.

Research question
Measured by
Target
Can they tell pre-approved from recommendations?
Sorting repair lines by type, on the first version each person sees
≥ 80% correct
Does recognising it change what they act on first?
Correct first click, and mentioning it unprompted after a five-second look
≥ 70% first clicks · ≥ 60% mention
Which version is faster with fewer wrong edits?
Prototype tasks on every version, scored automatically
≤ 1 edit to the wrong line · ease rating ≥ 5.5/7

The planning stage surfaced four things before a single session ran.

UnfairThe comparison wasn't fair yet.Version A showed errors but no recommendations, and B showed the reverse. Both now get the same data.
Vague"Understood" needed a behavior.It was defined as fetching parts for pre-approved work straight away, so it could be measured.
RiskTwo near-identical green labels."Approved at write-up" and "Approved" looked almost the same. The plan added a task that asks how each line got approved.
IdeaA variant C.A version that shows pre-approved work in a neutral color. It separates whether the new layout helps from whether the green color confuses.

Results: the Parts sessions are still running. I'll add which version won, and what changed in the shipped screen, when they report.

04 · Results

What exists now

A planner, not a timer.

Testify is now a seven-step tool, from Start to Results, in one self-contained file. It has eight activity types, including prototype tasks that score themselves. Remote sessions run through one published link, and results land in PostHog, Supabase or Google Sheets. Every prototype task gets heatmaps and click paths. An end-to-end test suite covers sessions, scoring, export and merging. I was also its first user, so I ran a heuristic audit of my own work against Nielsen's ten usability principles, and fixed what it found.

✓Contrast raised from about 3.3:1 to about 5:1 on secondary text.
✓Keyboard focus stays put. It used to jump to the top after every click.
✓Undo on deletes, and a visible save status.
✓Jargon I had invented, renamed. Counterbalance version order → alternate which version people see first. Blocks → activities.
✓Must-dos split from ideas. Also next-step banners, automatic setup with undo, export, predictions checked against results, and drag-to-tag.
Before · 3.3:1Optional. Testify names it from your goal if you leave this empty.
After · 5:1Optional. Testify names it from your goal if you leave this empty.
The same helper text, before and after the audit. The WCAG AA accessibility standard asks for 4.5:1 on body text.

Shipped as

One file

Seven steps, Start to Results, in about 470 KB, plus a small Cloudflare Worker (a server program) for publishing and sign-in. Participants don't need accounts.

Activity types

8

Including prototype tasks that score themselves, and sorting lines by type.

Before any session

1 flawed test

The two versions showed different data. The planner caught it on the first real study, before any sessions.

Fixes to my own tool

7 fixes

From the heuristic audit of my own tool.

Still to measure

Pending

How many participants it reached, which version won, and time saved per study compared with planning by hand.

Method: my own use across two real studies, a heuristic audit against Nielsen's ten usability principles, and an end-to-end test suite.

05 · Phase 3

Three days in October

From my planner to a tool someone else can run.

Over three days, October 16 to 18, Testify went from a planner only I could drive to a hosted tool with its own look, voice and participant flow. The bar I set was that a junior designer, new to research, should be able to plan and run a fair study with it.

What I changed

Fewer questions, fairer versions.

✓Setting up. Testify is now hosted online, with storage so old studies are kept. Participants share one link instead of getting one each. The code lives on GitHub, so I can work on it from the cloud or my PC as well as my Mac.
✓Fair prototypes. The Parts prototype now has three versions: the current screen, the proposed one, and one that shows pre-approved work in a neutral color. All three use the same realiztic data with no developer-only alerts, and the differences between them are easier to see.
✓Simpler for a junior designer. I audited the whole tool from the point of view of someone new to research. It now uses plain words and one question per screen, and I took out questions that didn't help. Targets are optional, and they're called targets instead of goals. The tagging screen is gone, and you can use screenshots when there's no prototype.
✓The flow. A new study starts with a chat that asks for its name, what you want to learn, and whether you have designs. Prototypes come after the questions. A viewer lets you flip between versions and take screenshots. A Check step confirms that PostHog, the analytics service, is recording. Next buttons say where they lead.
✓Look and voice. I made a branding deck to find the voice, then mixed its directions in my own way. The type is sharper, the palette is warm and cream, and each color has one job. Pink is only for the main action, violet is for links and highlights, and amber marks what needs attention. Long sections fold away. The layout follows my gestalt rules, based on how people see things as grouped: related things sit together, labels go on the left and actions on the right.
✓Feedback and control. The Save button shows when your work is saved. Marking something done brings a confirmation and an Undo option, and the Remove button now clearly looks like a remove action.
✓Participants. Answers are required by default, and any question can be set to Optional. Participants get a Back button, can zoom in on pictures, and see which version each question is about. A task finishes only when they take the right action or press "I'm stuck". The first-click activity ignores stray clicks, and a warning appears when an ad blocker stops the study. Confidence and ease questions stay off unless you ask for them. The task card lights up when the next task starts, because a prototype that reloads looking the same seems stuck.
✓Publishing. One Publish button gives a link participants can open, and Update republishes after a change, keeping the same link. There's no more downloading a file and uploading it to a web host.
✓Team sign-in. Coworkers sign in with their work email and automatically get the team's connections to the services that store results, with no setup codes or keys to paste. Studies stay private until shared. Each one can be shared with the whole team or with named people, with view or edit access. Viewers can duplicate a study to make their own copy.
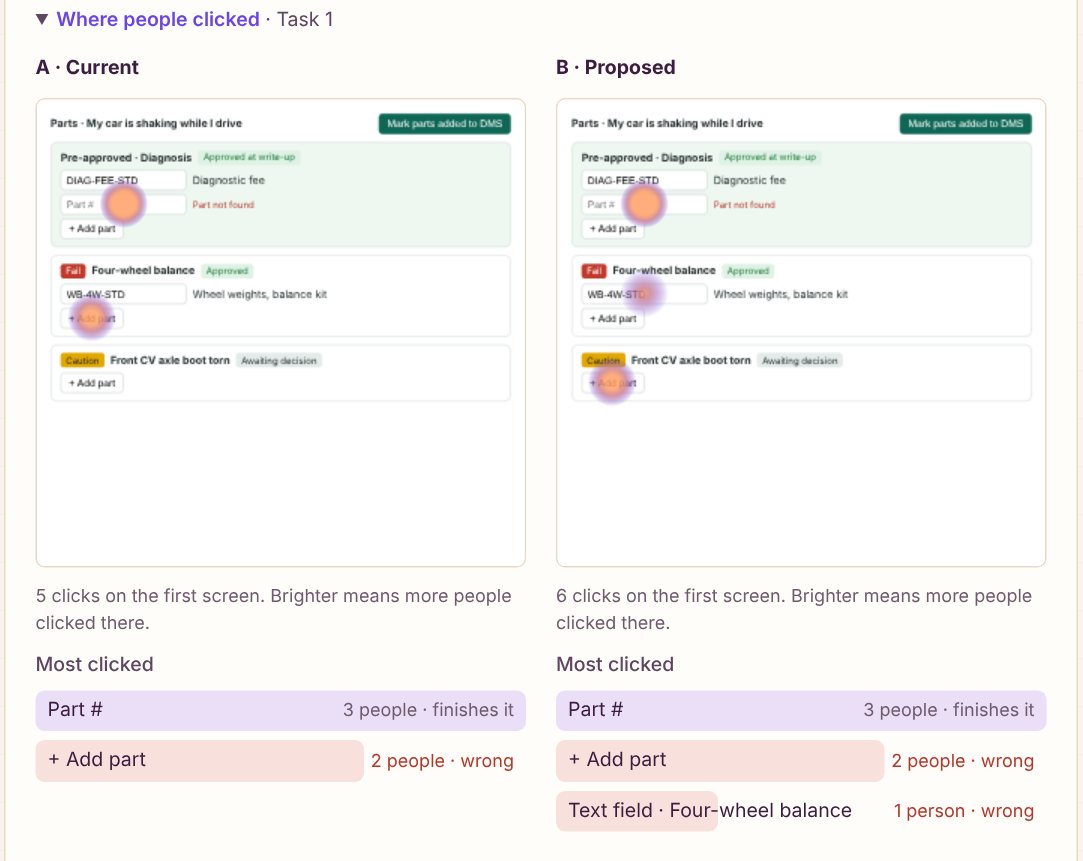
✓Results that say what to do. Each task gets a heatmap drawn over the real prototype, a list of the most-clicked controls with the wrong ones marked, and the most common click paths. The AI summary reads clicks and answers together. It comes back with what to change first, themes backed by word-for-word quotes, and what to look into next.
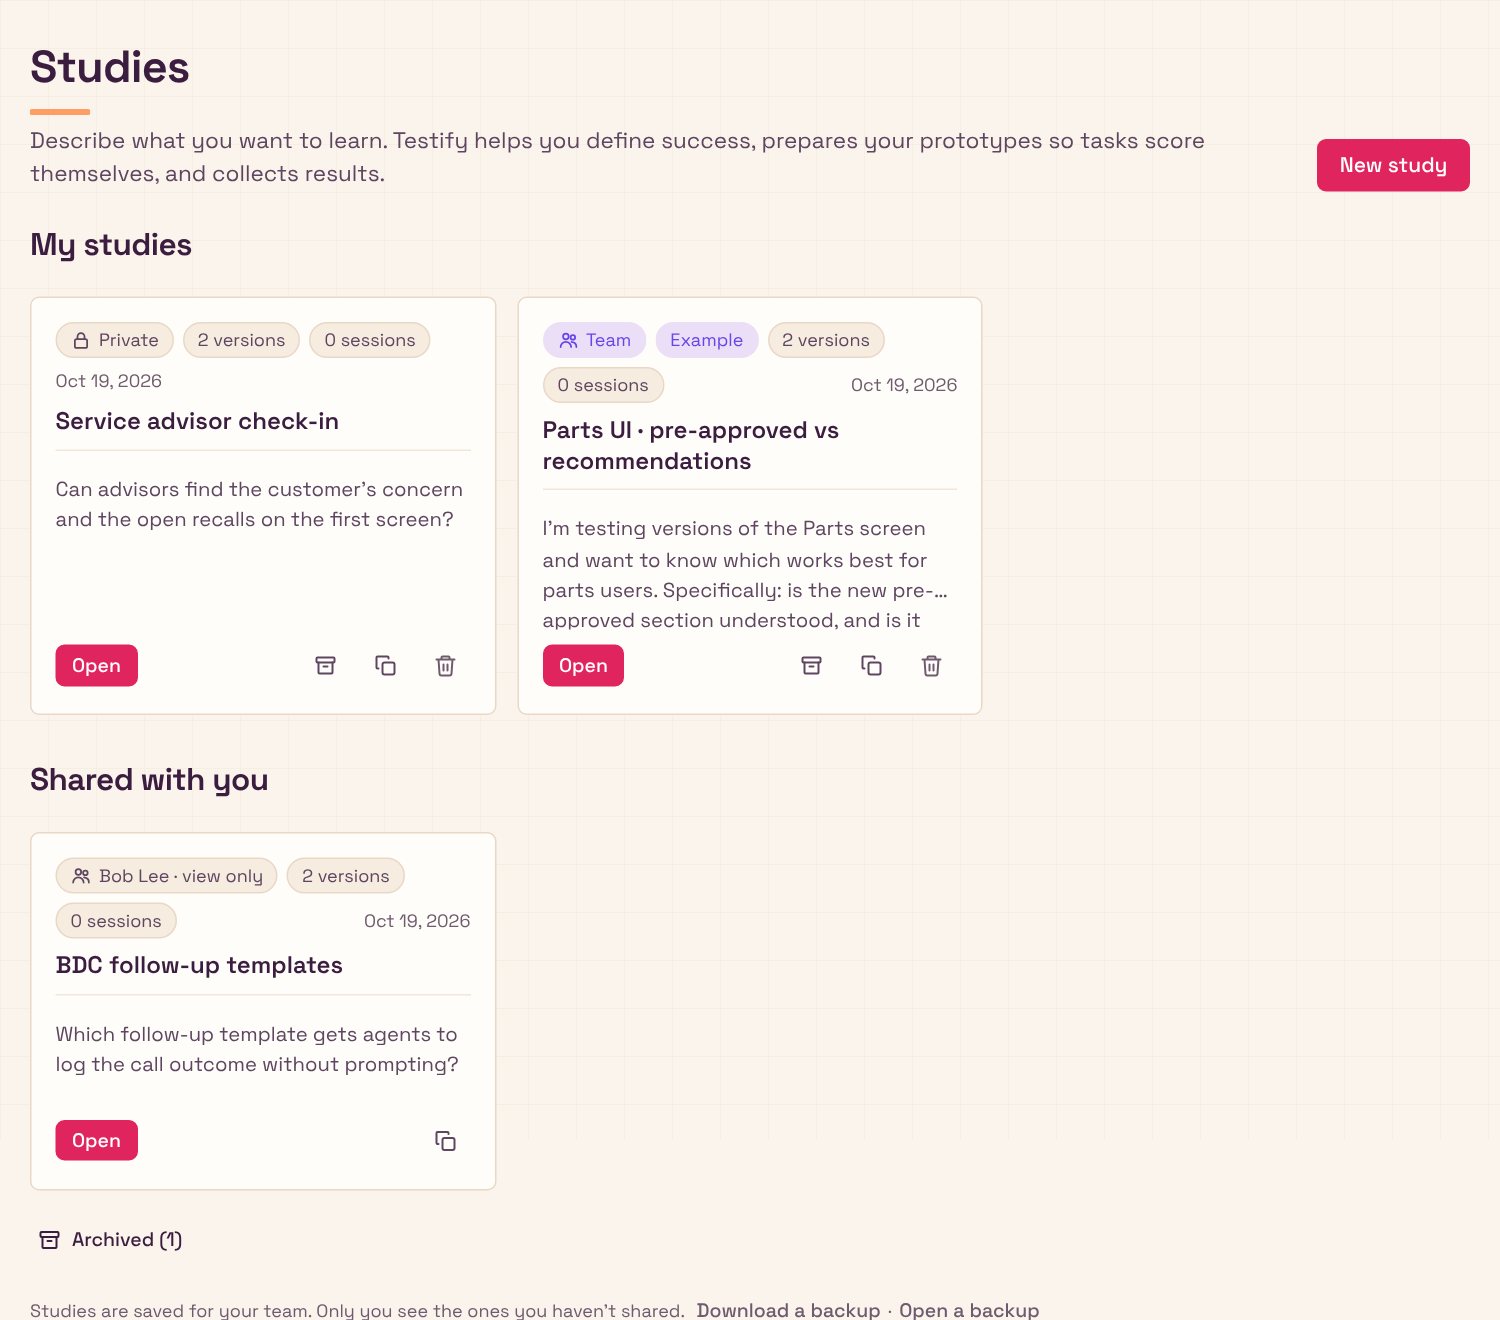
The studies home when signed in: My studies, each marked Private or Team, Shared with you from a teammate, and the archive.
Signed in: your studies, marked Private or Team, what teammates share with you, and the archive.
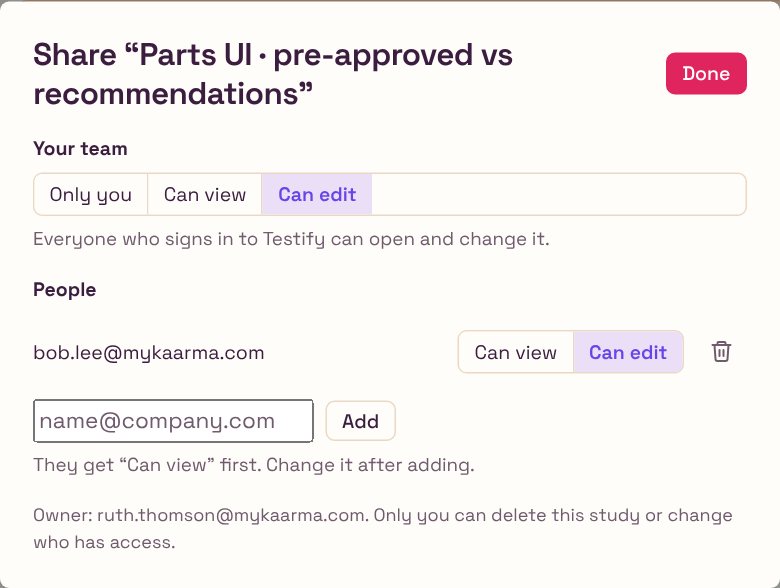
Sharing one study: the team can view or edit, plus a named person with edit access.
Each study is shared on its own, with the team or with named people, as view or edit.
Where people clicked on task 1: a heatmap over each version of the prototype, and the most-clicked controls with wrong ones marked.
Where people clicked, drawn over the real prototype. From six practice sessions, not real participants.

The look

Each color has one job.

The visual style is called Warm Studio. It uses the Space Grotesk typeface throughout, a cream page with a faint graph-paper grid, plum-colored text, crisp 6px corners and almost no shadow. This page uses the same style.

PinkMain actions only. As a highlight it read as an error. #E0245E
VioletLinks, selection, focus and highlights. #6A44E8
LilacSmall soft surfaces: chat replies, selected tabs. #EADFF7
AmberNeeds attention, never an error. #A64B0C
ApricotSmall decoration, like the heading underline. #FF9E64
Cream and plumThe page and the ink. #FBF4EC · #3B1D3F
Design decisions

Decisions that became features.

Method

  • Shuffle the design order.Each person sees the designs in a different order, so none always goes first.
  • Make targets optional.Comparing designs works on its own. Switch on Targets when you also want to ask “is it good enough?”
  • Always offer “Not sure”.Sorting questions include it, so a lucky guess doesn't count as right.
  • Show the AI the screens first.The AI sees the designs before it suggests follow-up questions, so its questions match what's actually on screen.

Fairness

  • Only the tested thing may differ.The Check step marks every other difference between versions as Intended or Fix, before anyone takes the study.
  • Alerts and placeholders count.An error message or broken image that appears in only one version gets flagged as a fix.

Voice and focus

  • A voice is a short set of rules.Testify states the fact first, then adds one line explaining why. Two sentences at most.
  • Keyboard focus isn't selection.The outline that shows where keyboard focus is has its own style, so it never looks as if something has been chosen.

Sharing

  • Share a link instead of a file.Publish once, then press Update after changes. The link never changes.
  • Sign-in is the setup.Teammates get the team's connections when they sign in, so there are no setup codes.
  • Private until shared.Every study shows a lock icon or a Team label, and can be shared with view or edit access.
  • A blank browser can't overwrite the team.The team's saved connections fill in anything missing, so opening Testify in a fresh browser never wipes the team's setup.

Data and privacy

  • Two kinds of analytics key.The key that sends answers is built into the participant page. The key that reads results stays private.
  • Trust only real replies.Some ad blockers quietly fake the analytics service's reply, so answers look sent when they aren't. Participants see a warning when that happens.
  • Record labels, never typing.Each recorded click stores the label on the control, such as a button's text, and never anything a participant typed.
  • Clicks need quotes.Results pair heatmaps and click paths with what people said, then suggest what to change.

Habit

01

Check the versions differ only in what you're testing before anyone takes the study.

Habit

02

Try the study yourself in Preview, then once for real in a clean browser with no saved data.

Habit

03

Publish once, then press Update after every change. The link stays the same.

Habit

04

Results can take a few minutes to arrive, so wait before deciding data is missing.

Habit

05

Write down what future sessions should know, so the tool's context doesn't live only in my head.

06

Differently

What I'd change with hindsight.

I'd have started with the planner. Phase 1 was a competent copy of tools that already exist. What was actually missing came before all of them, in the planning. I could have seen that from my own notes if I had read them as research.

I'd have split the Plan page into steps sooner. It is long, and the heuristic audit confirmed what I already felt every time I scrolled it.

What it doesn't do yet: it won't find participants for you, so you bring your own. Heatmaps cover each task's first screen only. And the AI summary still has to be judged on a real study rather than a sample one.

Next case study · Canvas Dashboard

A semester on one page.

Read the case study